AI read 400 years of old archives overnight and found a meteorite fall missing from every catalog
Give an AI agent a pile of digitized old documents and one question. It searches by meaning, narrows down candidate passages, reads and translates them, then checks them against the original scans. One software engineer used this approach on old documents and newspapers and found an 1812 meteorite fall missing from all six meteorite catalogs the engineer checked. Historian Benjamin Breen searched Dutch East India Company records and found a dodo hunt that belongs in the 1611–16 gap in the timeline of dodo sightings. Neither find has been confirmed by experts yet. Someone else used a single scan to read a cipher letter that had gone unread for 217 years. Here are the cases.
Oct 13, 2026·3 cases
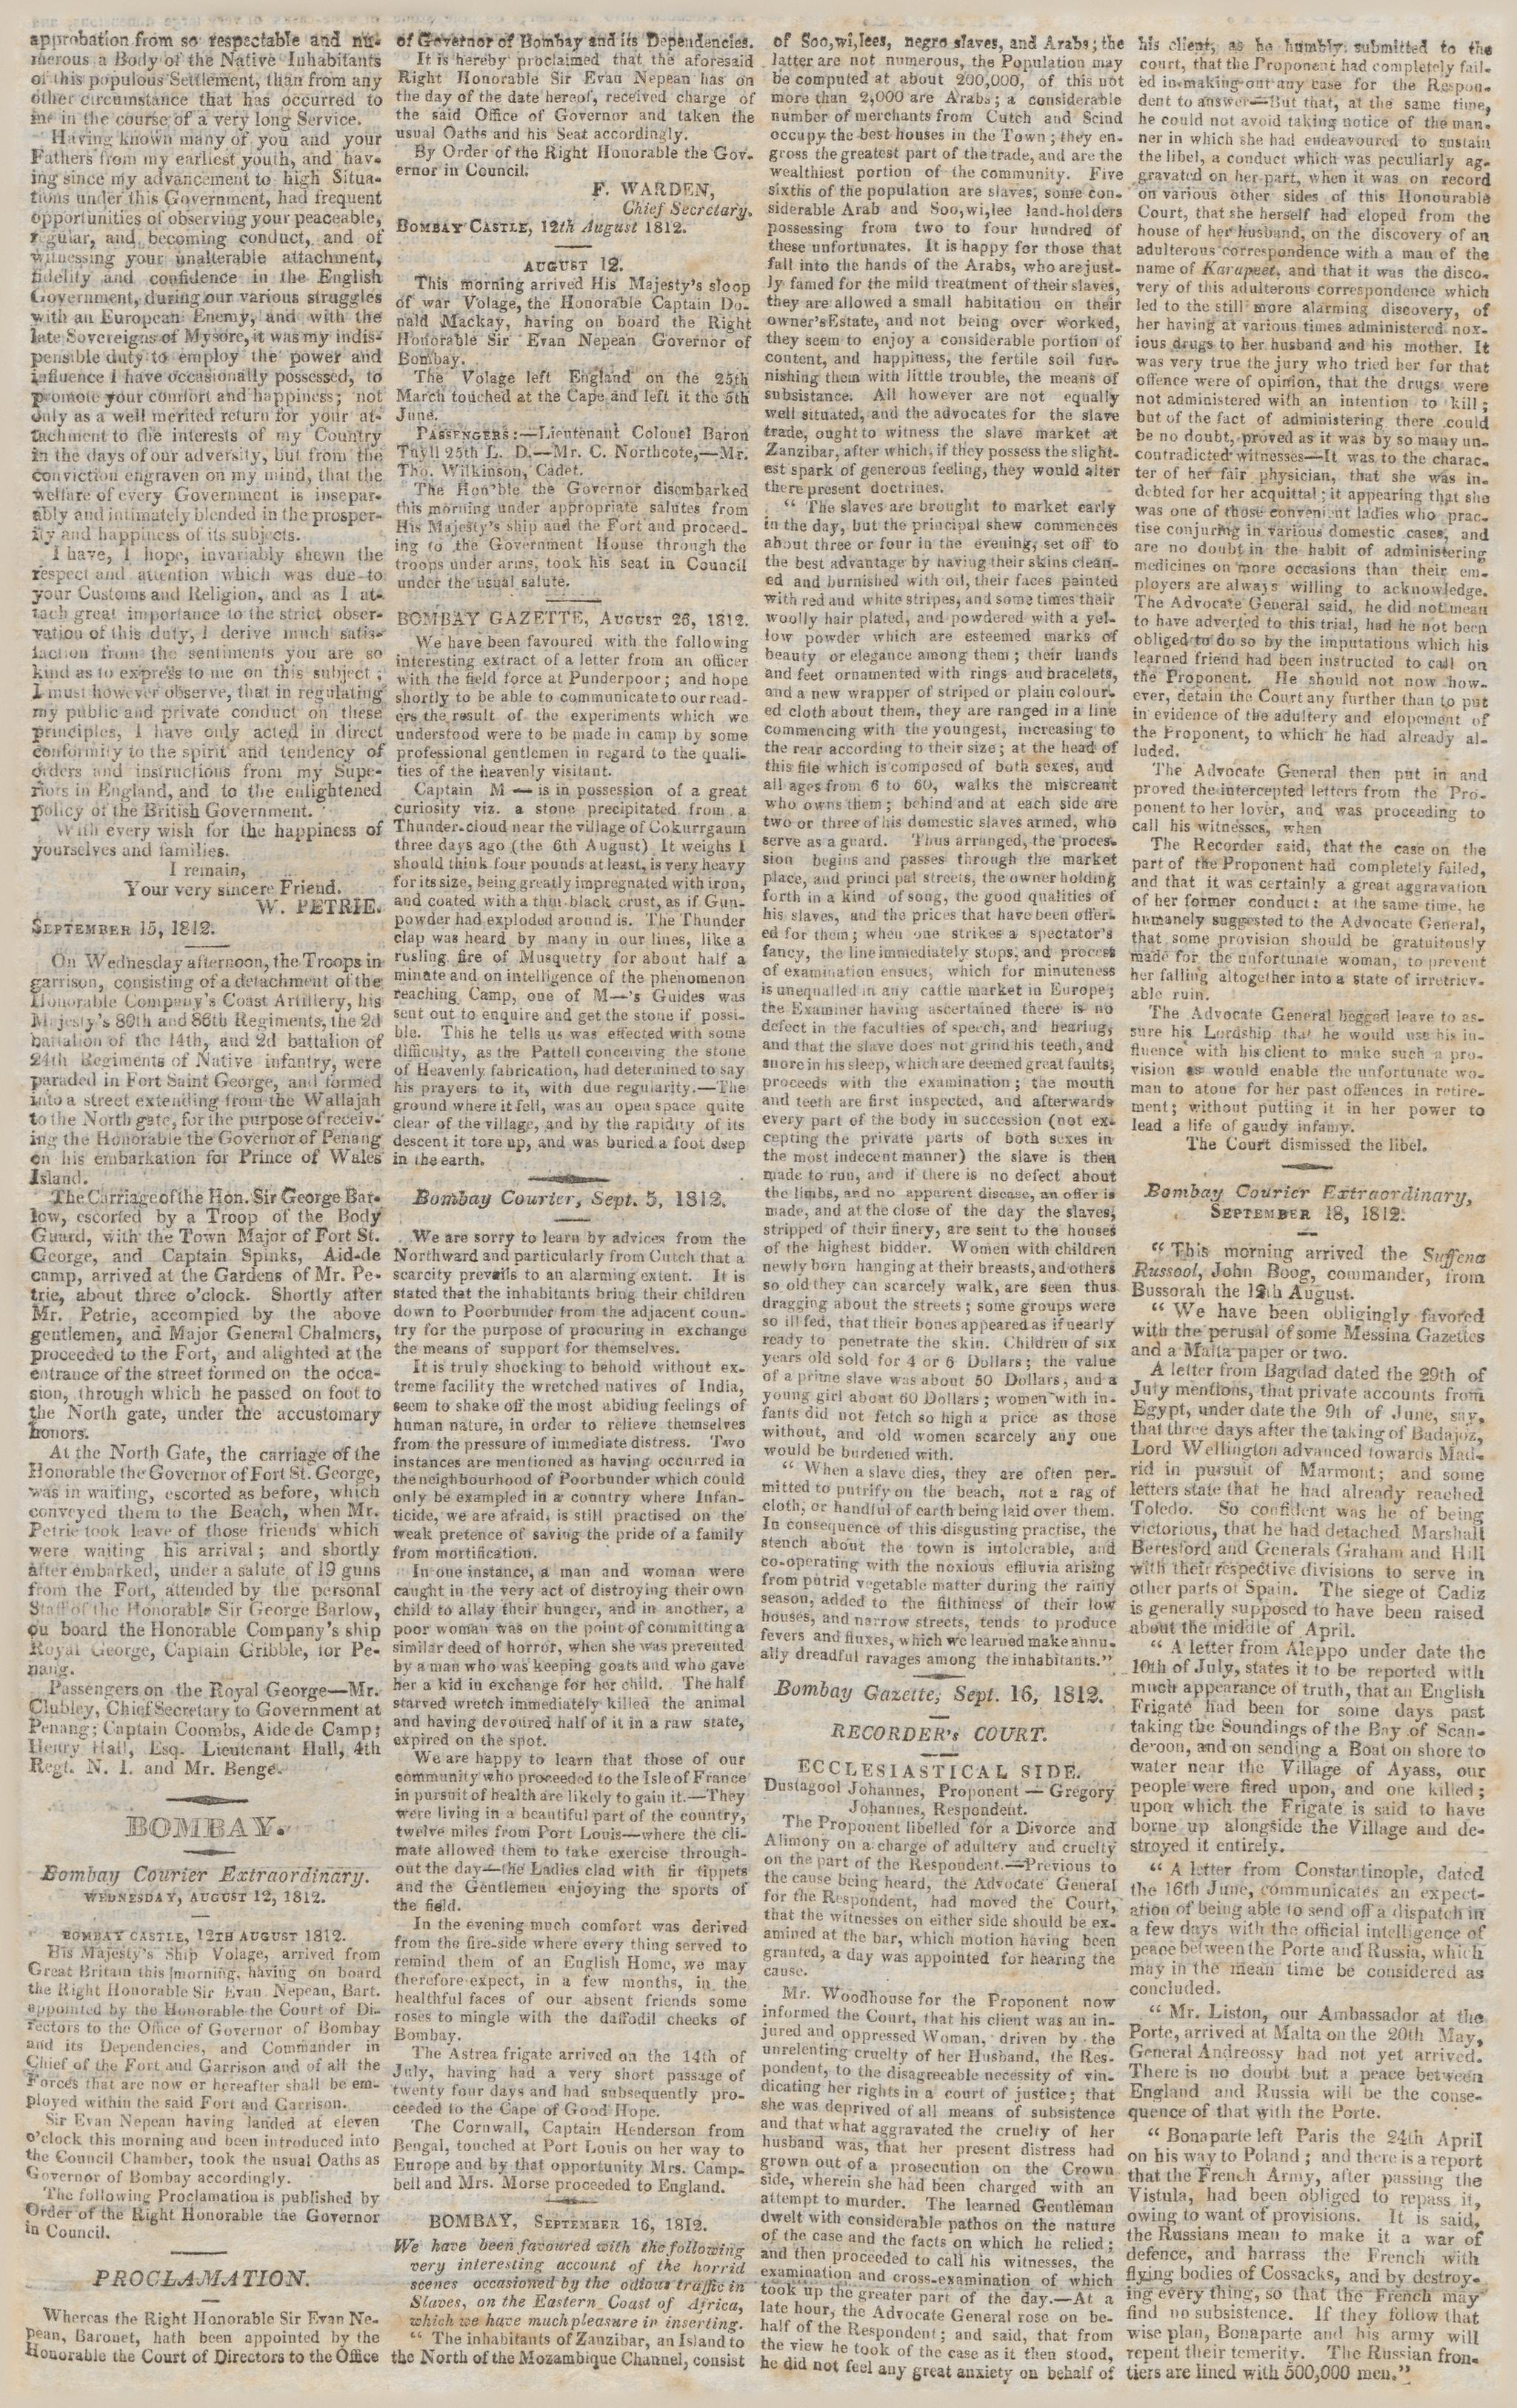
Page 3 of the Java Government Gazette, December 19, 1812. It carries a meteorite fall record missing from all six meteorite catalogs Waites checked. The original page is on Delpher (Royal Library of the Netherlands). Source: Jesse Waites's blog
The page at the top is page 3 of the Java Government Gazette from December 19, 1812. The article reprints a letter that had run in a Bombay newspaper that August. It reads: "a stone precipitated from a Thunder-cloud near the village of Cokurrgaum three days ago (the 6th August). It weighs I should think four pounds at least". Software engineer Jesse Waites found it while searching Dutch East India Company records and old newspapers with AI agents. The fall does not appear in any of the six meteorite catalogs Waites checked.
Several finds like this have come out over the past few weeks. On September 30, AI engineer Carter Church posted on X about using GPT-6 Astra to read a Napoleonic army cipher letter that had gone unsolved for 217 years, and the post passed 5.38 million views. On October 1, historian Benjamin Breen published a 1615 dodo hunting record found with an Opus 5.5 agent. A week later, Waites's meteorite post scored 184 points on Hacker News.
Here is the sequence Waites used. Build an index (embeddings) so old documents can be searched by meaning, pull a wide set of candidate passages, and filter them with a cheap model. Then a large model reads and translates them and checks them against the original scans. Breen had a large model rank the candidates pulled by embedding search, then reviewed that list by hand. In both cases, the people framed the questions themselves and decided for themselves what counted as a new discovery.
Reference 01Jesse Waites, software engineer in Boston · personal blog. Waites's post introducing Antiquity presents this project as a case study and carries a notice for JTPCK, a company that takes on custom AI document analysis work. Waites's relationship to JTPCK has not been disclosed.
One overnight pass over 4.35 million Dutch East India Company pages turned up rhinos and eruptions no list had recorded
After reading Breen's dodo post, Waites thought, "I can do this." The first step was asking a Deep Research assistant which historical questions could likely be answered with material already online. It came back with 13 candidates. Next, Waites built a pipeline with Claude Code. Index the documents with embeddings, search by meaning, filter with a small judging model called Jev, have Claude Haiku translate and extract dates and places, then have a Claude Code agent check each find against the original scans and match it with scholarly catalogs of meteorites and volcanoes.
Indexing 4.35 million pages of Dutch East India Company records, 5.7 million passages in all, took 12 hours overnight on a single GPU. By Waites's math, a person reading 8 hours a day, 5 days a week, at 2 minutes a page would need about 70 years to get through it. Filtering was cheap too. One search for animal records pulled up 59,000 passages that mention elephants, and having Jev read and sort them cost about $3. For meteorites, the searches used sentences like 'a heavy stone fell from the sky with a loud report,' according to JTPCK's case study page.
Before the real search began, Waites had the system re-find events that were already known: Breen's dodo record, the 1783 Laki eruption, and the 1815 Tambora eruption. If those came up, the search was working.
Three results came out of it. The first is the 1812 meteorite fall on the page shown at the top. That record came from an old newspaper, not the East India Company archives. Waites searched old newspaper articles along with the company records, and the meteorite story ran in one of those papers, the Java Government Gazette. The original page can be viewed on Delpher, the historical newspaper service of the Royal Library of the Netherlands. It is missing from all six meteorite catalogs. If confirmed, it comes 26 years before the earliest meteorite fall on record so far in Maharashtra, India, where Cokurrgaum is located.
The second is three Javan rhinos sent as gifts to the king of Kandy in Sri Lanka in 1738–1740. One was shipped in 1738 and two went aboard the Loverendaal in 1740, and all of them died before arriving. This shipment did not appear in any of the rhino record lists Waites checked. The third is volcanic eruptions. After filtering 769 eruption reports, 3 eruptions remained that are not in the Smithsonian's volcano catalog: Gamkonora in February 1722, Ciremai in early 1712, and Slamet in February 1780. The original rhino and volcano records are East India Company documents held by the National Archives of the Netherlands.
All three results are still candidates that no expert has reviewed. Waites has reached out to a meteorite curator, rhino researcher Kees Rookmaaker, and volcanologists, and is waiting to hear back. Waites also tried to pin down the great eruption of 1808–09, whose source volcano is still unknown. But even after the system read all 633 articles in Batavia's (now Jakarta) first newspaper, nothing relevant turned up.
Waites's question to the Deep Research assistant
which open historical questions are most likely to be solvable with data that already exists online?
The questions Jev asked when filtering animal mentions
Is this a real animal? Is it wild? Where is it?
Swap in three questions that fit what you are looking for. These were used to keep only real records out of tens of thousands of mentions.
Reference 02Benjamin Breen, associate professor of history at UC Santa Cruz · Res Obscura (Substack)
The dodo record had a five-year gap. AI dug through old records and found a 1615 hunt inside it
While preparing the dodo chapter of a book on animal extinction, Breen had an Opus 5.5 agent search the East India Company records in GLOBALISE. GLOBALISE is a project in which Dutch research institutions use AI to transcribe the company's handwritten documents and publish them for free. Breen also used GPT-6. As Breen explains it, agents like Opus 5.5 spin up several copies of themselves to divide up sources written in multiple languages, and given an API key, they run embedding searches on their own. On this project the agents multiplied to about a dozen.
The passage the agent found was in the April 1615 journal of the ship Wapen van Amsterdam. The crew wrote that on Mauritius they "caught many tortoises, dodos [dodeersen], and some geese and parrots". The original is among the East India Company documents at the National Archives of the Netherlands. The timeline of dodo sightings had been blank for 1611–16. Breen sees this passage as a new record for that gap and wrote, "I do think that this is a publishable result." In the comments, Breen added that, as far as they knew, the April 1615 passage had never been reported before.
The agent also reread known records in the original. In a 1638 document, 'velthoenderen' (a bird that appears to be the red rail) had been rendered as 'perdrix' (partridge) in an 1890 translation by a French scholar. Opus 5.5 went back to the original manuscript and corrected that translation. Neither the 1615 passage nor this correction has been formally reviewed by specialists in the field yet.
Reference 03Carter Church, AI engineer at SentinelOne · personal site
Given one scan and about six hours, GPT-6 Astra read a Napoleonic army cipher letter no one had read in 217 years
This case is not about searching a pile of documents. It is about reading one document that no one could read. Church gave GPT-6 Astra a single scan of a cipher letter addressed to General Marmont, published in a French military journal in 1969, and ran it for about six hours. Working from that one scan alone, the agent handled everything from transcribing the symbols to breaking the cipher. Church wrote, "I spent six hours of model time and a few evenings of my own".
The letter is made up of 1,300 cipher units using 155 distinct symbols. Only 33 symbol meanings had been published before, and those covered 435 of the 1,300 units. The agent worked out the remaining two-thirds or so from the letter itself. It produced the full text of the letter in French and English, and corrected the date, which had been misprinted in the 1969 reprint, to late March 1809.
Church also published a solution package with the key (key.tsv), the transcribed ciphertext, and verification scripts (verify.py and reproduce.py), so anyone can rerun it and check. The Israeli outlet Calcalist reported that Satoshi Tomokiyo, who runs the cipher research site Cryptiana, has marked the cipher as "solved."
How people reacted
What people liked
“The agents doing the grunt reading while you decide what matters feels like the actual division of labor.”
“For every amount of pages you have the time to read, an LLM provides a means to filter the set of pages you choose to read to a set that is more likely to be useful. It does not need to be perfect at it”
“As an AI "hater", I definitely think there are very useful and net-positive (and underrated yet) applications of the LLM technology. Finding something in archives is definitely one of those.”
“these kind of things are inspiring – especially if you are getting more confidence in that Mauritius-to-India link.”
A reporter on The New York Times visual investigations team. Breen also explored the hypothesis that dodos from Mauritius may have made it as far as the court of the Mughal emperor Jahangir in India.
Paste the request below into a coding agent like Claude Code or Codex. For practice material, GLOBALISE offers Dutch East India Company records for free.
Starter prompt
I want AI to dig through a pile of records using the method in this article.
https://www.working-ref.com/en/library/archive-agents-2026-10
Suggest three questions worth exploring in records I have [e.g., internal meeting notes, customer inquiries, old documents]. When I pick one, start right away. First, re-find something whose answer is already known to confirm the search works. Then cast a wide net, filter with a cheap model, and check anything the large model reads against the originals. If there is nothing for me to pick, start like the first case: search the GLOBALISE Dutch East India Company records for meteorite falls missing from the catalogs.
Share this reference
Weekly
Weekly · Free
Collect
Verify
BEST picks
Your inbox
Was this reference helpful?
The week in AI: the BEST just 3, straight to your inbox
Work Smarter with AI
You're in See you in your inbox with the next issue.